AI News

Latest updates from the world of artificial intelligence

COST PER MILLION OUTPUT TOKENS $0.50 GLM-5.3-Flash $25 Claude Opus 5 $30 GPT-5.6 Sol BITSMINDS.COM
Models

GLM-5.3-Flash vs Claude Opus 5 vs GPT-5.6 Sol

Z.ai’s new open-weight model scores 57.0 on the Artificial Analysis Intelligence Index — six points behind Claude Opus 5 and under two behind GPT-5.6 Sol, at $0.15 per million input tokens. It loses the flagship fight and wins the one that matters for volume: it beats Sonnet 5, Terra and Luna outright.

Artificial Analysis

Read more →
OX ALPHA GLM-5.3-FLASH BITSMINDS.COM
Models

GLM-5.3-Flash Is Ox Alpha: 320B, Multimodal, MIT

The stealth model that appeared on OpenRouter under the provider name “stealth” has a name at last. Z.ai’s GLM-5.3-Flash is a 320-billion-parameter multimodal mixture-of-experts model with a million-token context window and MIT-licensed weights — reportedly, a preview served entirely on Chinese-made accelerators.

MarkTechPost

Read more →
APACHE 2.0 WEIGHTS GRANITE 4.2 3B 8B 30B BITSMINDS.COM
Models

IBM Granite 4.2 Ships Agentic RL Under Apache 2.0

IBM published three open-weight models — 3B, 8B and 30B — with a switchable thinking mode across the family and reinforcement learning inside real software-engineering, terminal and web-search sandboxes for the two larger sizes. The 30B scores 57.0 on SWE-Bench Verified, and the whole family runs on hardware you own.

The Decoder

Read more →
LISTED ON OPENROUTER Ox Alpha BUILT BY 1M CONTEXT FREE TEXT IMAGE VIDEO No lab has claimed it since the August 20 preview BITSMINDS.COM
Models

Ox Alpha Is Free, Frontier-Class, and Unclaimed

A reasoning model with a million-token context window appeared on OpenRouter on August 20 under the provider name "stealth". Five days later, no lab has admitted building it.

TechCrunch

Read more →
GEMINI 3.7 Flash 34.4% → 43.6% FRONTIERCODE 1.1 BITSMINDS.COM
Models

Gemini 3.7 Flash Ships 3 Weeks After 3.6, at Half Price

Google shipped Gemini 3.7 Flash just three weeks after 3.6 Flash, claiming a jump from 34.4% to 43.6% on FrontierCode and from 49% to 65.3% on DeepSWE — and priced the introductory tier at half what 3.6 Flash cost.

Google

Read more →
31.4% ON 50K TOKENS GLM-5.3 SAME 743B BASE BITSMINDS.COM
Models

GLM-5.3: 6× on Terminal-Bench, Same 743B Base Model

Z.ai shipped GLM-5.3 on August 14 without retraining its base model. Every gain comes from scaled post-training — and on the company’s own coding benchmark it edges past Claude Opus 4.8 while spending roughly 60% fewer output tokens.

MarkTechPost

Read more →
Claude Opus 5 vs Fable 5 vs Sonnet 5: One Prompt Each
ModelsLab

Claude Opus 5 vs Fable 5 vs Sonnet 5: One Prompt Each

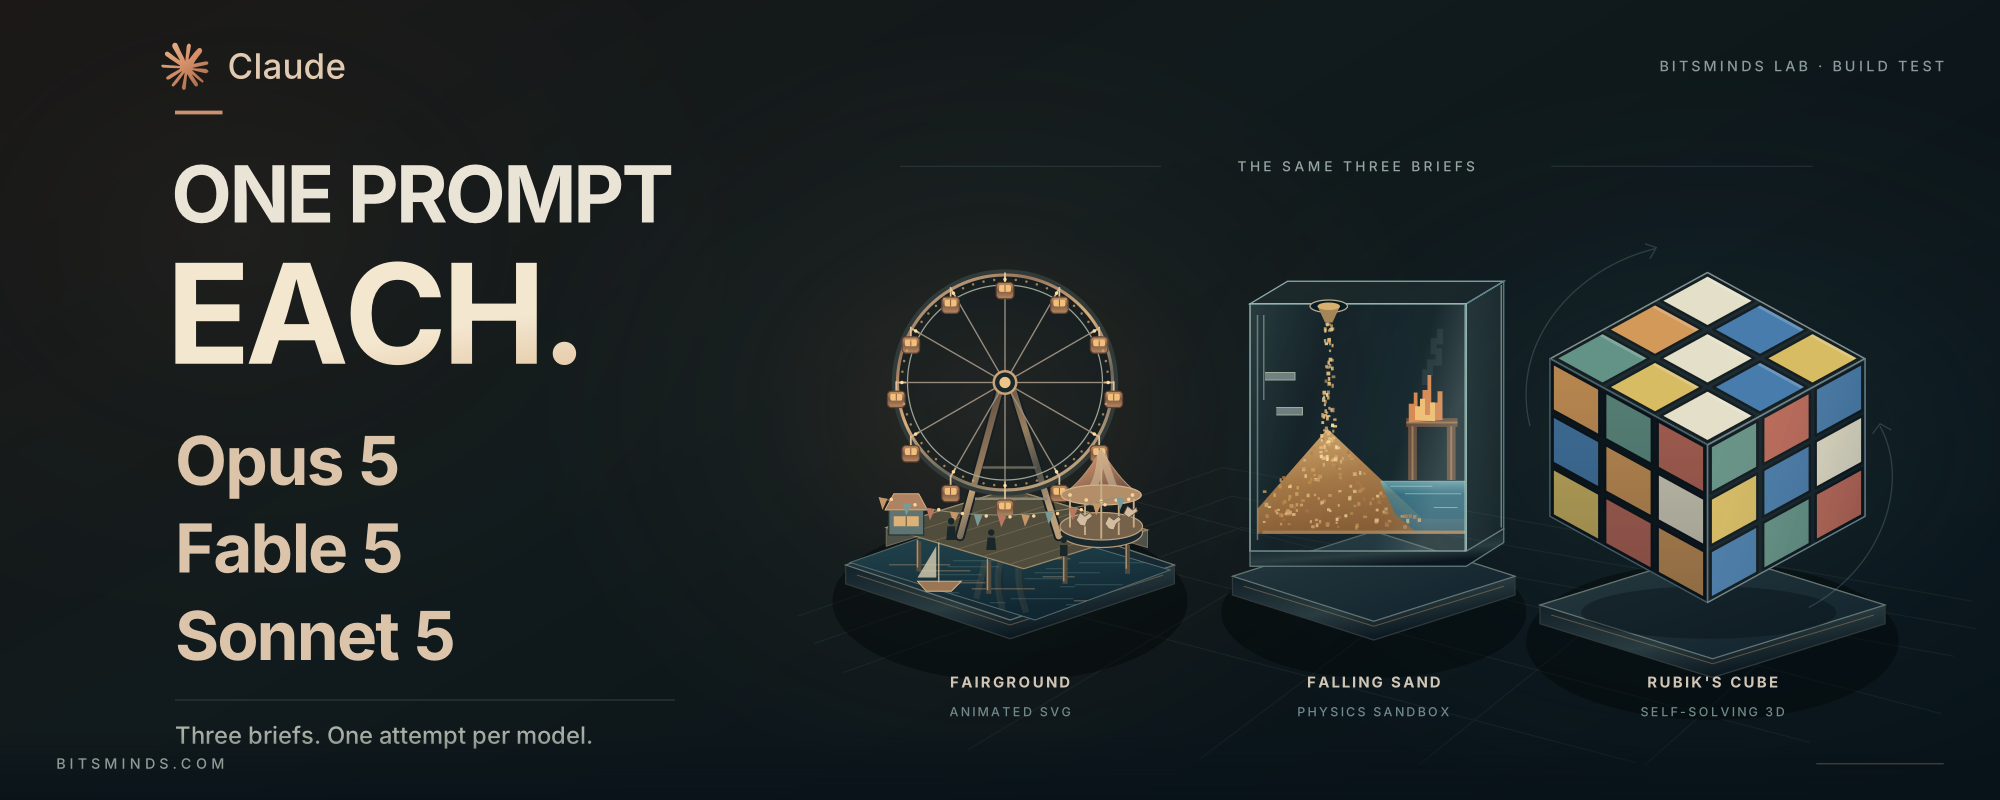
We gave Claude Opus 5, Fable 5 and Sonnet 5 the same three build briefs — an animated SVG fairground, a falling-sand physics sandbox and a self-solving Rubik’s cube — one run each, no retries, no browser. All nine builds run live inside the article. Opus 5 takes it 8–6–3, and the biggest surprise is the clock: the largest model was the fastest on every round, by a factor of nearly three.

BitsMinds Lab

Read more →
$0.87 / 1M OUTPUT V4-PRO-0813 GENERALLY AVAILABLE BITSMINDS.COM
Models

DeepSeek Shipped V4-Pro Without Telling Anyone

No blog post, no changelog, no press release — just an edit to the API pricing page. DeepSeek-V4-Pro-0813 is now generally available at $0.87 per million output tokens, with benchmark gains that nobody outside DeepSeek has reproduced.

OpenRouter

Read more →
SPACEXAI Grok 4.6 BITSMINDS.COM
Models

Grok 4.6 vs Opus 5 vs GPT-5.6 Sol: Frontier, 60% Cheaper

Artificial Analysis scored Grok 4.6 at 61 on its Intelligence Index — level with GPT-5.6 Sol at max, behind Fable 5 at 62 and Opus 5 at 63. It costs $2/$6 per million tokens against $5/$25 and $5/$30, and finishes long agentic tasks in ~53 turns where Opus 5 takes ~103. It also trails both rivals by eight points on the hardest software-engineering evals.

Artificial Analysis

Read more →
OPENAI · DAYBREAK PROGRAM Two tiers, one very sharp model DAYBREAK BLUE GPT-5.6 Sol, safeguards tuned for authorized defensive work 2.0% advanced cyber completion DAYBREAK RED GPT-5.6-Cyber, for exploit validation under monitoring 95.0% advanced cyber completion Unmodified GPT-5.6 Sol: 1.5% · Last year's GPT-5.5-Cyber: 57.3% · Rated High, below Critical BITSMINDS.COM
Models

OpenAI’s GPT-5.6-Cyber Found Two Chrome Zero-Days

OpenAI split its Daybreak security program into Blue and Red tiers and handed the Red tier a purpose-trained model that clears 95% of advanced cyber tasks — against 1.5% for the same frontier model with its guardrails intact.

The Decoder

Read more →
META · OPEN WEIGHTS · APACHE 2.0 Muse Glimmer 30B agentic model, small enough for one consumer GPU 4-bit · 19.8 GB full weights · 55 GB RTX 5090 3.1× faster Apple M5 Max 1.8× faster Apple M4 Max 1.5× faster BITSMINDS.COM
Models

Meta's Muse Glimmer Runs a 30B Agent on One GPU

Meta released Muse Glimmer under Apache 2.0 — a 30-billion-parameter agentic model distilled from Muse Spark that quantises under 20 GB and runs on a single consumer GPU.

Meta AI Research

Read more →
OPENAI · PREPAREDNESS FRAMEWORK The Critical rung is no longer ruled out WORK PAUSED LOW MEDIUM HIGH CRITICAL Every prior frontier model evaluated at High or below. BITSMINDS.COM
Models

OpenAI Can't Rule Out Critical Cyber Risk in Astra

OpenAI slowed work on its next frontier model after internal evaluations suggested Astra may cross the Critical cybersecurity threshold — a level no model has triggered before. Weights are locked down, some internal work is paused, and outside evaluators are being called in.

TechCrunch

Read more →
Shieldstral Mistral's 3B open-weights safety guard — you write the policy at runtime policy.txt "Flag content that promotes violence or self-harm." plain language, at inference 3B Apache 2.0 open weights calibrated score 0.97 BLOCK one forward pass, yes/no logits 84.9 F1 text · 83.8 F1 multimodal · 12 languages · runs on one 16 GB GPU BITSMINDS.COM
Models

Mistral's Shieldstral: A 3B Guard That Reads Your Policy

Mistral's new open-weights safety classifier takes the moderation policy as a plain-language prompt at inference time — no retraining — and matches guard models seven times its size while running on a single 16 GB GPU.

Mistral AI

Read more →
MAI PLAYGROUND · HIDDEN EARLY ACCESS MAI-Realtime does not take turns. It listens and speaks together. OUT · SPEAKS IN · LISTENS hears you barge in never waits for a pause SAME INSTANT VOICES Victoria · Grant LANGUAGES 17, switched mid-sentence STATUS unannounced, no pricing BITSMINDS.COM
Models

Microsoft's MAI-Realtime Aims at OpenAI's Voice Slot

A hidden entry in Microsoft’s MAI Playground reveals MAI-Realtime, a full-duplex speech model that listens and speaks simultaneously across seventeen languages, with two configurable ways of deciding whose turn it is. Microsoft has confirmed nothing — but the component it would displace inside Azure’s Voice Live service is OpenAI’s GPT-Realtime.

TestingCatalog

Read more →
QWEN3.8-MAX Weights next week.
Models

Alibaba Opens Qwen3.8-Max to the World — and Says the Weights Come Next Week

The 2.4-trillion-parameter flagship went broadly available today through Alibaba Cloud's APIs and the new QwenWork beta, with open weights promised for next week. The parameter count is the least interesting part: this is Alibaba reversing course after keeping recent flagships closed. The performance claim behind it — second only to Claude Fable 5 — still has no independent benchmark, and would require a 14-point jump in one generation.

South China Morning Post

Read more →
AI & MATHEMATICS · OPENAI ‘ASTRA’ Ten Problems, Decades Old Theorem. machine-checked ×10 This time the proof comes with a receipt.
Models

OpenAI Names Its Next Model Family Astra — and Says It Solved Ten Decade-Old Math Problems

An internal version of Astra resolved ten open problems across group theory, high-dimensional geometry, coding theory, quantum complexity, lattice cryptography and extremal combinatorics, OpenAI says — with the proofs formalised in Lean as machine-checkable certificates. That is a genuine methodological upgrade over May's Erdős result, which rested on expert sign-off. It also leaves the one question a proof checker cannot answer.

The Decoder

Read more →
OPEN MODELS · DEEPSEEK V4 FLASH They Didn't Make It Bigger same model, same price what it scores Nothing about it grew. It got better anyway.
Models

DeepSeek Gained Ten Index Points Without Changing the Model — and Undercut Luna a Day After Its 80% Cut

DeepSeek V4 Flash 0731 scores 50 on the Artificial Analysis Intelligence Index, up from 40 in April, with identical architecture, the same 13B active parameters and the same price list — the gain came entirely from post-training. It now sits one point behind GPT-5.6 Luna at roughly 60% lower cost per task, with a 98% cache discount. The nuance most coverage will skip: accuracy was unchanged, and the jump came mainly from a reduced hallucination rate.

Artificial Analysis

Read more →
GPT-5.6 · API PRICING Prices Just Fell 80% Only one of them got cheaper.
Models

OpenAI Cut Luna's Price 80% and Left Sol Untouched — the GPT-5.6 Range Is Now 25× Wide

GPT-5.6 Luna drops to $0.20 / $1.20 per million tokens from $1 / $6, and Terra to $2 / $12 from $2.50 / $15. Sol is unchanged, and its new Fast option costs twice as much for about 2.5× the speed. OpenAI credits serving efficiency — but a roughly 20% cost improvement explains Terra's cut and comes nowhere near explaining Luna's, which leaves the gap between the cheapest and best model five times wider than it was a month ago.

OpenAI

Read more →
BENCHMARKS · ARC-AGI-3 Same Model. Same Test. retained reasoning compaction same benchmark Two switches. Three times the score.
Models

OpenAI Says Two Settings Tripled Its ARC-AGI-3 Score — ARC Prize Says That Isn't the Same Test

OpenAI reported that enabling retained reasoning and compaction in its Responses API took GPT-5.6 Sol from a 13.3% baseline to 38.3% on ARC-AGI-3's public set, using roughly six times fewer output tokens — a figure above Claude Opus 5's 30.2% record. ARC Prize says its official scores use a standardised setup with no provider-specific settings, and François Chollet allows general-purpose API settings only if clearly reported. Both sides have a point, and the comparison still isn't apples to apples.

OpenAI

Read more →
MOONSHOT AI · KIMI K3 2.8 Trillion. Now Free. Weights live on Hugging Face Now find a machine that can run it
Models

The Largest Open Model Ever Just Went Free: Kimi K3's 2.8-Trillion-Parameter Weights Are Live

Moonshot AI published Kimi K3's full weights on Hugging Face at 00:00 UTC on July 27, exactly as promised — 2.8 trillion parameters under Apache 2.0, the biggest open-weight release in history. It lands three days after 50 companies signed a letter defending open models, and days after the White House accused Moonshot of distilling an Anthropic model to build it.

Moonshot AI

Read more →
CLAUDE OPUS 5  vs  GPT-5.6 One Dial vs Three Models Claude Opus 5 vs GPT-5.6 Sol Terra Luna So which lineup actually wins?
Models

Claude Opus 5 vs GPT-5.6: One Dial vs Three Models

OpenAI split GPT-5.6 into Sol, Terra and Luna. Anthropic shipped one model with an effort dial. Put both on the same cost-independent index and the settings line up exactly — including one result that should change how you configure your API calls.

BitsMinds Analysis

Read more →
BITSMINDS ANALYSIS · CLAUDE LINEUP Opus 5 vs Fable 5 vs Sonnet 5 What actually changed — on price, specs, and the benchmarks Claude Fable 5 $10 / $50 33.7% Claude Opus 5 $5 / $25 43.3% Claude Sonnet 5 $3 / $15 not measured Opus 4.8 · legacy $5 / $25 18.7% Bars: Frontier-Bench v0.1 (coding), as published by Anthropic All three current models share a 1M-token context · prices per million input / output tokens
Models

Claude Opus 5 vs Fable 5 vs Sonnet 5 vs Opus 4.8: The Benchmark Comparison

Opus 5 costs the same as the Opus 4.8 it replaces, beats the double-priced Fable 5 on Anthropic's own coding charts, and burns a fraction of the tokens doing it. We lined up every published number — specs, prices, benchmarks — and flagged exactly where the comparisons don't hold.

BitsMinds Analysis

Read more →
ANTHROPIC · OFFICIAL LAUNCH Claude Opus 5 Is Here The rumors were right — here’s what actually changed
Models

Claude Opus 5 Is Officially Here — 1M Context, a New 'xhigh' Mode, and the Rumors Were Right

Anthropic launched Claude Opus 5 on July 24, replacing Opus 4.8 as its workhorse model: a 1-million-token context window, a new 'xhigh' reasoning-effort level above today's max, and unchanged $5/$25-per-million-token pricing. The 'Honeycomb' leak, the Vertex AI sightings, and the specs rumor all turned out accurate — Fable 5 remains Anthropic's top-tier model.

Anthropic

Read more →
GOOGLE · GEMINI Three Flash models ship… …while Gemini 3.5 Pro is still nowhere to be seen 3.6 Flash −17% output tokens 3.5 Flash-Lite cheap · beats Gemini 3 3.5 Flash Cyber finds & fixes bugs Gemini 3.5 Pro promised June · still not shipped → Meanwhile, Google says it has begun its biggest pretraining run yet — Gemini 4 Shipped July 21 via the Gemini API & Gemini Enterprise · the price war grinds on
Models

Google Ships Three New Gemini Flash Models — but 3.5 Pro Is Still Missing, and It's Already Pretraining Gemini 4

On July 21 Google released Gemini 3.6 Flash, 3.5 Flash-Lite, and a security-tuned 3.5 Flash Cyber — useful, cheap, efficient. But the flagship Gemini 3.5 Pro is still nowhere to be seen, months past its June target, and Google says it has already begun its most ambitious pretraining run yet: Gemini 4.

Google

Read more →