AI News

Latest updates from the world of artificial intelligence

GPT-6 family build-off: Astra, Sol and Luna, represented by a crystal star, a golden sun and a silver crescent, on one silver astronomical instrument against a midnight-blue sky. Original vector editorial illustration for BitsMinds. The three equal-height instruments symbolize the GPT-6 family. Their shared base represents the shared build briefs; dimensions and celestial forms do not encode scores or performance. OpenAI logo outline preserved verbatim from the project asset. Static, self-contained SVG with no raster, filters, scripts or external dependencies. GPT-6 THE FAMILY BUILD-OFF OpenAI Astra Sol Luna VS VS BITSMINDS LAB SAME BRIEFS. THREE MODELS. BITSMINDS.COM
ModelsLab

GPT-6 Astra vs Sol vs Luna: Is the Discount Worth It?

OpenAI's two cheaper GPT-6 models took on the three briefs GPT-6 Astra answered in September, and the flagship won every round. Astra finished with 10 points, Sol took 5 and Luna took 3, the same order as the price list. Sol and Luna built each brief two to six times faster, and every one of their six builds shipped a fault you can see.

BitsMinds Lab

Read more →
SOL GPT-6 LUNA BITSMINDS.COM
Models

GPT-6 Sol and Luna Arrive at Half the Price of GPT-5.6

OpenAI released GPT-6 Sol and GPT-6 Luna on 22 September at $2/$10 and $0.10/$0.50 per million tokens, half what their GPT-5.6 predecessors cost. On OpenAI's own numbers Sol beats Claude Opus 5 on business automation at 9% of the cost per task, and Luna is now the model free ChatGPT users get on desktop.

OpenAI

Read more →
A NEW LEADER Opus 5.5 vs Fable 5.1 vs Astra 6 BITSMINDS.COM
ModelsLab

Opus 5.5 vs Fable 5.1 vs Astra 6: We Have a New Leader

Claude Opus 5.5 beat Fable 5.1 and GPT-6 Astra on the three briefs this series gives every frontier model: 10 points to Fable’s 9 and Astra’s 8. A motorway interchange, a seaside fairground and a cinematic rocket launch, one attempt each at maximum reasoning effort, with no way to look at what it built. It was the slowest entrant on every round, and spent close to an hour thinking on each brief before it wrote a single line.

BitsMinds Lab

Read more →
Claude Opus 5.5 — a new chapter A monumental copper Claude starburst is suspended inside a sculpted ivory paper ring. Dozens of finely separated pages rise from a stepped circular plinth, then converge into one smooth copper-edged ribbon. Warm light catches the paper layers and brushed copper, casting a long architectural shadow. Large dark typography reads Claude Opus 5.5, with the confirmed input and output list prices and one-million-token context below. The sculpture is an editorial metaphor for reasoning and efficiency, not a diagram or benchmark claim. Original self-contained vector artwork for https://www.bitsminds.com/news/claude-opus-5-5-launch-price-benchmarks-2026. Release: 22 September 2026. Price text reflects the article's standard API list prices, USD per million tokens. Official Claude outline preserved verbatim from the project logo. No raster assets, animation, filters or external dependencies. ANTHROPIC Claude Opus 5.5 $4 in · $20 out per million tokens 1M context BITSMINDS.COM
Models

Claude Opus 5.5 Is Here: Cheaper Than Opus 5, and Better

Anthropic shipped Claude Opus 5.5 on 22 September at $4 and $20 per million tokens, a fifth under Opus 5 and ahead of it on every benchmark it published. The sticker fell 20% but Anthropic claims a task costs 40% less, because the model also spends fewer tokens getting there. Every number here is Anthropic's own.

Anthropic

Read more →
Hill Climb: three labs, three little worlds Three miniature cross-sections of game terrain sit side by side on an ivory field. An orange open-top jeep with a helmeted driver climbs a sunset ridge for Claude Opus 5. An orange rover with its small cab below the chassis crosses a moonlit pine forest for GPT-5.6 Sol. A teal number-47 buggy drives through a canyon for Grok 4.7. Coins, star badges, suspension springs and exposed layers of rock make each scene feel like a small working model. The official model-provider marks and model names appear above. Original editorial illustration inspired by the article's screenshots, without scores or simulated rankings. Original SVG illustration for https://www.bitsminds.com/news/claude-opus-5-vs-gpt-5-6-sol-vs-grok-4-7-hill-climb-2026. Three game builds are the subject, not benchmark results. All artwork is vector; brand paths retained from project assets. 47 Opus 5 GPT-5.6 Sol Grok 4.7 BITSMINDS.COM HILL CLIMB
ModelsLab

Opus 5 vs GPT-5.6 Sol vs Grok 4.7: Can They Build a Game?

The same one-file game brief from September, handed to three models that had never attempted it: one from Anthropic, one from OpenAI, one from xAI. All three passed every requirement the brief actually stated. All three then missed something it did not. Play all three builds in the article.

BitsMinds Lab

Read more →
Grok 4.7, Fable 5.1 and Astra 6 — can it compete? An editorial model-making bench holds a miniature motorway interchange, a copper Ferris wheel and a rocket travelling outside a camera frame. A thick clay-orange cable ends in two separated connectors in the foreground, representing the gap between working mechanisms and visible results in Grok's builds. The words Can it compete? sit to the left. The official Grok, Claude and OpenAI marks label the three entrants along the bottom. The miniatures are original illustrations, not screenshots or quantitative comparisons. Original vector editorial illustration for BitsMinds Lab. Article: https://www.bitsminds.com/news/grok-4-7-vs-fable-5-1-vs-astra-6-build-off-2026. Based on the supplied article and published comparison. No benchmark scores are encoded in the composition. CAN IT COMPETE? Grok 4.7 Fable 5.1 Astra 6 VS VS BITSMINDS.COM
ModelsLab

Grok 4.7 vs Fable 5.1 vs Astra 6: Can It Compete?

SpaceXAI’s Grok 4.7 took the three briefs this series has handed every frontier model — a motorway interchange, a seaside fairground and a cinematic rocket launch — against Claude Fable 5.1 and GPT-6 Astra. One attempt each, maximum reasoning effort, no looking at what they built. Every mechanism Grok was asked for is present and computed correctly. In all three, the thing a viewer actually watches was never connected to it.

BitsMinds Lab

Read more →
SPACEXAI Grok 4.7 $2 IN · $6 OUT PER MILLION TOKENS BITSMINDS.COM
Models

Grok 4.7 Chases Fable 5.1 at a Fraction of the Price

SpaceXAI released Grok 4.7 on 21 September at exactly the price Grok 4.6 carried — $2 per million input tokens and $6 per million output. It beats its predecessor on every benchmark the company published, trails Claude Fable 5.1 on most of them, and costs a fifth as much to feed and an eighth as much to read.

SpaceXAI

Read more →
Claude: three names, one unconfirmed rumour A warm paper evidence folder bears the official Claude mark. Three removable labels read Fable 5.2, Opus 5.2 and Opus 5.5 with a question mark. Beside them, a large brass and charcoal magnifying glass reveals another question mark on a blank specimen card. The illustration represents changing names and missing confirmation, not an announced model. Original vector editorial illustration for https://www.bitsminds.com/news/claude-opus-5-5-rumour-three-names. Article context: 21 September 2026. Model names are rumoured. Claude mark uses the unchanged outline from the project logo asset. Fable 5.2 Opus 5.2 Opus 5.5? BITSMINDS.COM
Models

Claude Opus 5.5: One Rumour, Three Names in 16 Days

Anthropic shipped Claude Opus 5.5 on 22 September at $4 and $20 per million tokens — the price and the day the leak named. The sixteen days before it were a different story: one unconfirmed release, three different names, and a chain that had already been wrong about two of them.

Anthropic model documentation

Read more →
Step 5 1M CONTEXT · WEIGHTS OPEN OCT 15 BITSMINDS.COM
Models

StepFun Ships Step 5 Preview, a 600B Agent Model

The Shanghai lab has put a 600-billion-parameter sparse mixture-of-experts model behind a live API, with 27 billion parameters active per token, a one-million-token context window and open weights promised for 15 October. Artificial Analysis scores it 44 on its Intelligence Index, at $1.00 per million input tokens.

MarkTechPost

Read more →
Many kinds of input, one Qwen context On a deep violet field, a filmstrip, an audio waveform, a landscape photograph and a text page curve toward a single luminous sphere bearing the official purple Qwen star. A label below reads “1M context”, representing text, images, audio and video sharing one million-token context window. Aa 1M context BITSMINDS.COM
Models

Qwen3.8-Omni-Flash Undercuts Gemini on Audio and Video

Alibaba shipped an omni-modal model that takes text, images, audio in 113 languages and two-hour video into one million-token context, at $0.15 per million input tokens — five times under Gemini 3.8 Flash. Its agentic perception reads long video selectively, gaining accuracy while cutting tokens 45.7%. The weights are not open.

MarkTechPost

Read more →
Hill Climb: GPT-6 Astra versus Claude Fable 5.1 A teal desert buggy climbs a sandstone ridge on the left. An orange jeep climbs a green hill on the right, under an arc of gold coins. The two landscapes meet at a diagonal divide. 7 GPT-6 ASTRA CLAUDE FABLE 5.1 VS HILL CLIMB BITSMINDS.COM
ModelsLab

GPT-6 Astra vs Claude Fable 5.1: Who Builds a Better Game

Both models rebuilt the same racing game from one brief. One chose a muted desert, the other bright arcade colour. Both are playable here. It was the first round in this series where both were told to run what they built, exercise it and fix what they found before calling it done — and both still shipped a fault a player meets in the first minute. Fable 5.1 took it 15–14, the narrowest result this series has recorded.

BitsMinds Lab

Read more →
Gemini 3.8 Live: thinking while the conversation continues An editorial illustration in a dark blue and violet room. A carefully drawn studio microphone and a tilted smartphone flank a translucent speech bubble carrying the multicoloured Gemini star. A continuous luminous audio waveform travels between them. Above the bubble, a separate arc connects small search, reasoning and completion symbols, representing background work continuing during a spoken conversation. The phone screen and visual paths are conceptual, not a reproduction of Google's actual interface or internal reasoning. Original vector illustration for BitsMinds, gemini-3-8-live-extended-thinking-voice. 16 September 2026. GEMINI 3.8 LIVE EXTENDED THINKING Gemini 3.8 LIVE The conversation continues Thinking. Still talking. BITSMINDS.COM
Models

Gemini 3.8 Live Tops Voice AI and Undercuts GPT

Google’s new speech-to-speech pair takes the top of the Artificial Analysis quality index — and the cheaper sibling runs at about a seventh of GPT-Live-1 Astra’s hourly cost. Both reason in the background without stopping the conversation.

Google

Read more →
Atria Dawn Preview 744B · MIT · shipped with no announcement BITSMINDS.COM
Models

Atria Dawn: A 744B Agent Model, Shipped in Silence

Shanghai AI Laboratory dropped a 744-billion-parameter, MIT-licensed agent model on GitHub with no announcement at all — then published a 143-author technical report three days later. It tops five of 16 benchmarks and trails Claude Opus 5 badly on code.

arXiv

Read more →
Anthropic model cadence: waiting for the next beat A sculpted terracotta metronome with the Claude symbol stands on a warm cream surface. Beside it, a solid model cartridge reads Fable 5.1, released 1 September. An outlined, translucent future cartridge reads Fable 5.2 with a prominent question mark and the word Unconfirmed. Six small solid beats represent the six models released since April. The image illustrates a release pattern and an unconfirmed rumour, not an announced model or launch date. ANTHROPIC MODEL CADENCE / 2026 RELEASE RHYTHM ANTHROPIC The next beat? A release pattern. A rumour. An open question. FABLE 5.1 RELEASED / 01 SEP 2026 FABLE 5.2 ? UNCONFIRMED NO OFFICIAL ANNOUNCEMENT SIX RELEASES SINCE APRIL BITSMINDS.COM
Models

No Fable 5.2 Yet, but Anthropic’s Cadence Says Soon

Anthropic has announced no Fable 5.2, and no Opus 5.1 or 5.2 either: the docs list four current models and nothing newer. The rumour rests on a single X account whose first date already passed. But the company has shipped six frontier models since April at a median gap of 24 days, which puts the next one due right about now.

Anthropic model documentation

Read more →
SAKANA AI · FUGU MAX + ULTRA V2 One API, a pool it won’t name BITSMINDS.COM
Models

Sakana's Fugu Ultra v2 Routes Around Astra and Fable

The Tokyo lab shipped two orchestrators on September 11: a cost-first Fugu Max at $2 per million input tokens, and a capability-first Ultra v2 that takes best or joint-best on five of eight benchmarks with Claude Fable 5, Fable 5.1 and GPT-6 Astra deliberately kept out of its pool.

Sakana AI

Read more →
Claude Sonnet 5 vs GPT-5.6 Terra: Middle-Class Fight
ModelsLab

Claude Sonnet 5 vs GPT-5.6 Terra: Middle-Class Fight

The same three build briefs, one attempt each, no browser — but handed to the middle of each lab’s range instead of the top. Anthropic’s Claude Sonnet 5 and OpenAI’s GPT-5.6 Terra both broke the same fairground ride in the same new way, and one of them shipped a game that never runs. All six builds are live in the article.

BitsMinds Lab

Read more →
Claude Opus 5 vs GPT-5.6 Sol: Not Even Close
ModelsLab

Claude Opus 5 vs GPT-5.6 Sol: Not Even Close

Claude Opus 5 and GPT-5.6 Sol got the same three build briefs — a playable Pac-Man, an animated seaside fairground and a motorway interchange — one attempt each, with no browser to check their own work. All six builds run live in the article: play both games, watch the rest, and see which one holds up.

BitsMinds Lab

Read more →
Astra 6 Fable 5.1 VS BITSMINDS.COM
ModelsLab

GPT-6 Astra vs Claude Fable 5.1: There Can Be Only One

OpenAI’s GPT-6 Astra and Anthropic’s Claude Fable 5.1 got the same three build briefs — a motorway interchange, a seaside fairground and a cinematic rocket launch — one attempt each, at maximum reasoning effort, and neither could open a browser to check its own work. All six builds run live inside the article, faults and all: a bridge that hides a truck mid-crossing, a carousel that is not doing what it looks like it is doing, and two rockets with very different ideas of what a launch is. Score it yourself.

BitsMinds Lab

Read more →
Claude Fable 5.1 vs Opus 5 vs Sonnet 5: One Point Apart
ModelsLab

Claude Fable 5.1 vs Opus 5 vs Sonnet 5: One Point Apart

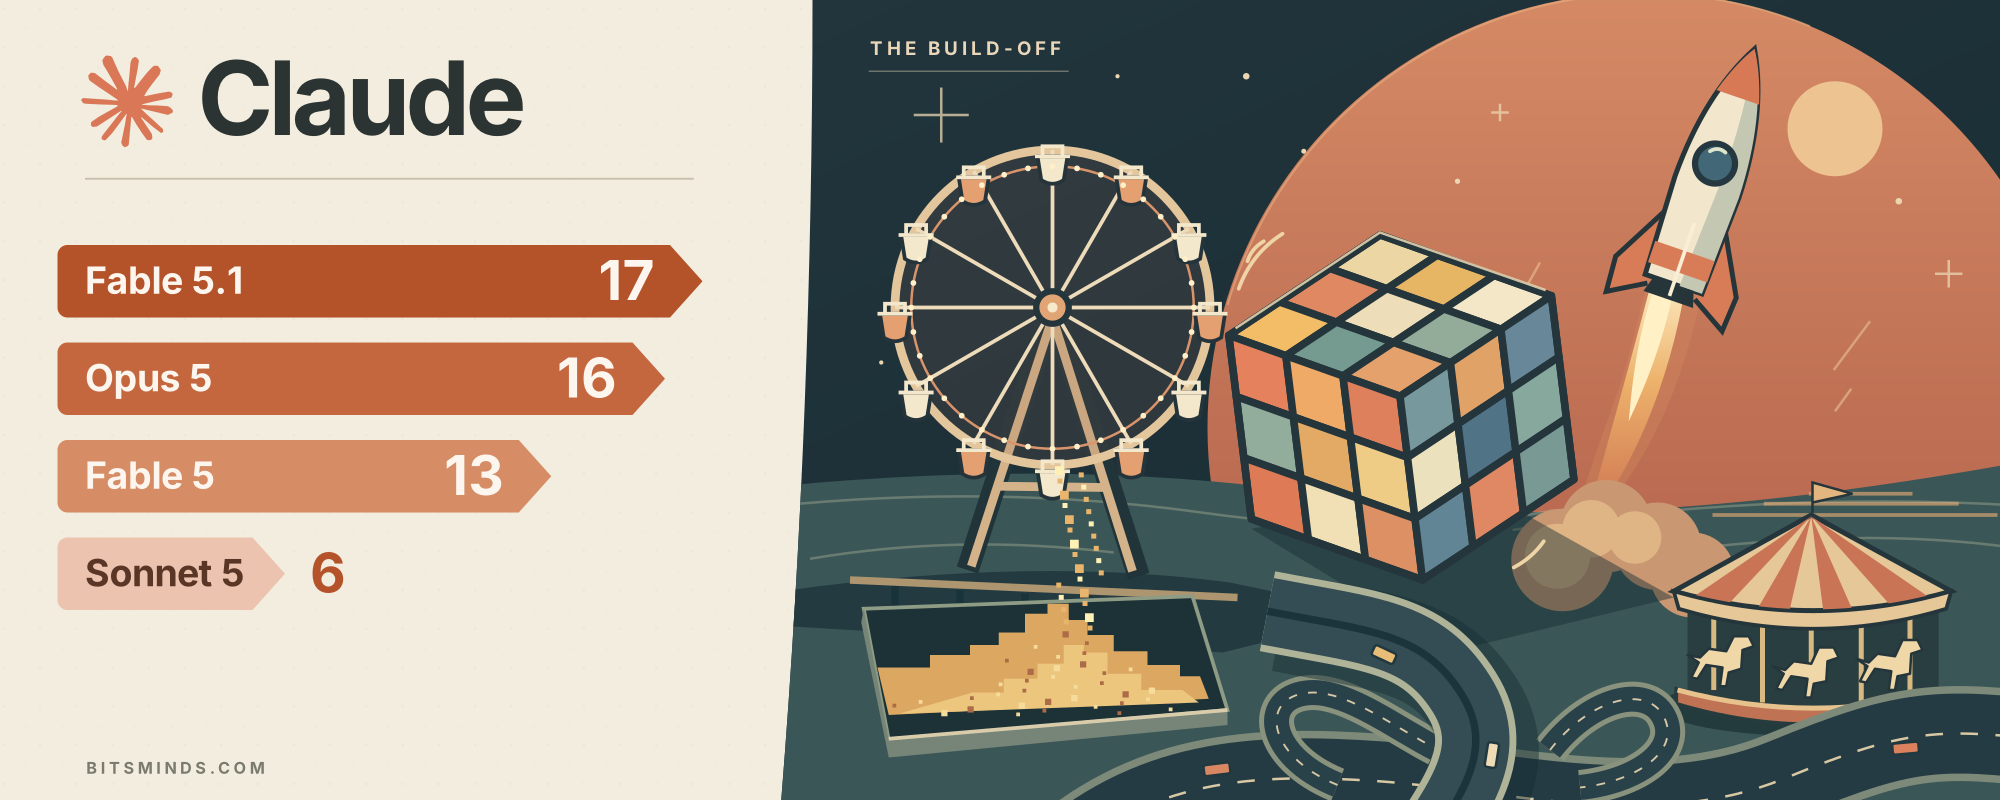
We gave four Claude models — Fable 5.1, Opus 5, Fable 5 and Sonnet 5 — the same five build briefs at maximum reasoning effort, one attempt each, with no browser to check their work. All twenty builds run live inside the article. Fable 5.1 won four of the five rounds and finished only a single point clear, because the round it lost was the one where its code never ran at all.

BitsMinds Lab

Read more →
GPT-6 ASTRA OPENAI · "WELCOME TO THE AGI ERA" ARC-AGI-3 99.9 COMPUTER USE BITSMINDS.COM
Models

GPT-6 Astra Lands and OpenAI Declares the AGI Era

OpenAI's largest training run ever produced a model that drives a computer at superhuman speed and is the first rated Critical on cyber. Independent scoring puts its intelligence level with the model it replaces — at 2.5x the price.

Axios

Read more →
MUSE SPARK 1.3 DeepSWE 75.4 · 1M context · $0.10 / 1M contributor tier BITSMINDS.COM
Models

Meta's Muse Spark 1.3 Leads Coding at $0.10 a Million

Meta's fourth frontier model in five months takes the top spot on DeepSWE, near-saturates million-token retrieval, and undercuts every rival on price — as long as you let Meta train on your traffic.

The Register

Read more →
WORLD LABS ATLAS An omni world model 1440p 60 sec 3D BITSMINDS.COM
Models

Fei-Fei Li’s World Labs Unveils Atlas World Model

Atlas is a single model that generates a minute of 1440p camera-controlled video, reconstructs scenes in 3D from a handful of photos, and outputs point clouds and Gaussian splats — beating specialist reconstruction models on their own benchmark.

World Labs

Read more →
OPENAI ASTRA Preparedness Framework · cybersecurity EXPLOITBENCH 100% ZERO-DAYS FOUND 2 LOW MEDIUM HIGH CRITICAL CAPABILITY THRESHOLD REACHED BITSMINDS.COM
Models

Astra Is OpenAI’s First Model Rated Critical on Cyber

OpenAI says Astra is the first large language model to cross the Critical cybersecurity tier of its Preparedness Framework, scoring 100% on ExploitBench and discovering two zero-days on its own. Advanced cyber access goes to alpha testers first.

OpenAI

Read more →
ANTHROPIC Fable 5.1 SMARTER AGENT · SAME PRICE · CHEAPER CACHE TERMINAL-BENCH 55.8% CACHE −75% SEPTEMBER 1, 2026 BITSMINDS.COM
Models

Fable 5.1: Anthropic Doubles Its Science-Agent Score

Anthropic’s Fable 5.1 doubles Terminal-Bench-Science, tops every published head-to-head against GPT-5.6 Sol, cuts cache reads 75% — and ships beside Mythos 5.1, a candidly riskier sibling for vetted defenders.

Anthropic

Read more →