AI News

Latest updates from the world of artificial intelligence

RUMOR WATCH · UNCONFIRMED Claude Opus 5 — the evidence board Cursor · Jul 9 “Claude Honeycomb EAP” — then gone Vertex AI · ×2 listing spotted twice, vanished both times 5? the next flagship? 1M context? leaked, unverified “xhigh” mode? launch “this week”?? No official API ID · no system card · every thread on this board is still a rumor
Models

Claude Opus 5 Rumor Watch: The 'Honeycomb' Leak, a Reported 1M Context, and Talk of a Launch This Week

The internet is convinced Claude Opus 5 ships any day now — a model codenamed 'Honeycomb' surfaced briefly in Cursor and a Google Vertex AI listing, with leaked talk of a 1M-token context and an 'xhigh' reasoning mode. Here's the honest version: what's actually been spotted, what's pure speculation, and why the timing rumor won't die.

Leak Reports

Read more →
MOONSHOT AI · OPEN WEIGHTS Kimi K3 The largest open-weight model ever — now #1 at frontend code, ahead of Fable 5 #1 Frontend Code Arena · 1,679 pts · ahead of Fable 5 2.8T · MoE 1M context 16/896 active Weights Jul 27 Open weights on Hugging Face · native multimodal · $0.30/$3 in · $15 out per million tokens
Models

Moonshot's Kimi K3 Is the Largest Open-Weight Model Ever — and It Just Beat Fable 5 at Frontend Code

China's Moonshot AI released Kimi K3, a 2.8-trillion-parameter open-weight mixture-of-experts model — the biggest ever — that took the #1 spot on Arena.ai's Frontend Code leaderboard at 1,679 points, ahead of Claude Fable 5. It has a 1M-token context, activates just 16 of 896 experts per token, and full weights are promised on Hugging Face by July 27.

Moonshot AI

Read more →
SPACEXAI · CODING & AGENTS Grok 4.5 Opus-class coding — at fast-model speed and a fraction of the cost AVG. OUTPUT TOKENS · SWE-BENCH PRO TASK Opus 4.8 67k Grok 4.5 16k 4.2× fewer tokens $2 / $6 per 1M tokens 80 TPS output speed #1 SWE Marathon Trained alongside Cursor · Terminal-Bench 2.1 83.3% · SWE-Bench Pro 64.7% · free for now in Grok Build & Cursor
Models

SpaceXAI's Grok 4.5 Bets on Efficiency Over the Crown — Opus-Class Coding at 4.2× Fewer Tokens

Grok 4.5, trained alongside Cursor, doesn't top the leaderboards — Fable 5 and GPT-5.5 still edge it on raw coding benchmarks. But it resolves SWE-Bench Pro tasks in about 15,954 output tokens versus ~67,020 for Opus 4.8, is served at 80 tokens/sec, and costs just $2/$6 per million tokens. xAI's pitch: Opus-class results at a fraction of the time and cost.

xAI

Read more →
PRISMML · ON-DEVICE AI Bonsai 27B A 27B multimodal model that runs on your phone — fully offline ~54 GB · FP16 1-BIT QAT multimodal · 262K context 3.9 GB · 1-bit Native low-bit QAT · keeps >90% of full precision · 11 tok/s on iPhone 17 Pro · Apache 2.0 on Hugging Face
Models

PrismML's Bonsai 27B Squeezes a 27-Billion-Parameter Model Onto Your Phone — at 3.9GB, Fully Offline

PrismML has open-sourced Bonsai 27B, a 1-bit build of Qwen3.6-27B that shrinks a model needing ~54GB at full precision down to 3.9GB — small enough to run on an iPhone at 11 tokens/sec while keeping more than 90% of full-precision performance. It's multimodal, handles a 262K-token context, and ships under Apache 2.0.

PrismML

Read more →
THINKING MACHINES LAB · MIRA MURATI Inkling An open-weight, multimodal foundation model — built to be customized OPEN WEIGHTS · APACHE 2.0 975B MoE · 41B active 1M token context 45T tokens · 4 modalities Text · Image · Audio · Video  •  download on Hugging Face, fine-tune on Tinker
Models

Mira Murati's Thinking Machines Releases Inkling — a 975B Open-Weight, Multimodal Model Built to Be Customized

Thinking Machines Lab's first broadly available model is open. Inkling is a 975B-parameter mixture-of-experts model (41B active), trained on 45T tokens of text, image, audio, and video, with a 1M-token context — released under Apache 2.0 and tuned on the lab's Tinker platform.

Thinking Machines Lab

Read more →
BYTEDANCE · IMAGE GENERATION Seedream 5.0 Pro China’s new flagship reasons about prompts — and renders native 2K Native 2K 14 languages $0.075 / image GPT Image 2-level Prompt reasoning · point-and-lasso editing · on-image text · native 2K output
Models

ByteDance's Seedream 5.0 Pro Pushes China to the Front of AI Image Generation

ByteDance's new flagship image model reasons about prompts, edits with point-and-lasso precision, writes on-image text in 14 languages, and outputs native 2K — at $0.075 an image. Observers already put its quality at GPT Image 2 level.

TestingCatalog

Read more →
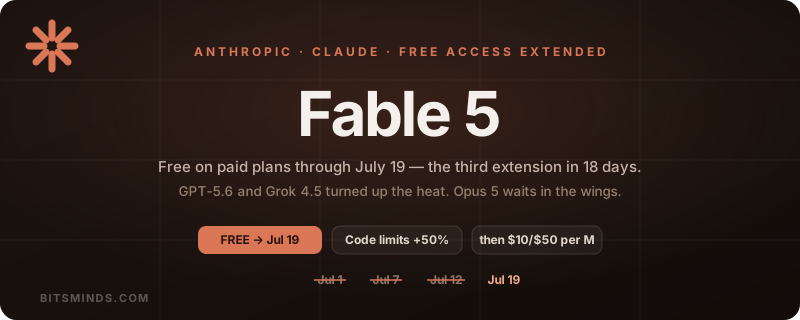
Anthropic Extends Free Fable 5 Again — the Deadline That Keeps Moving
Models

Anthropic Extends Free Fable 5 Again — the Deadline That Keeps Moving

Anthropic pushed free Fable 5 access to July 19 — its third extension in 18 days — as GPT-5.6 undercuts it on price and Grok 4.5 goes live. An Opus 5 leak in Cursor fuels the theory that the extensions are a bridge to the next flagship.

Anthropic

Read more →
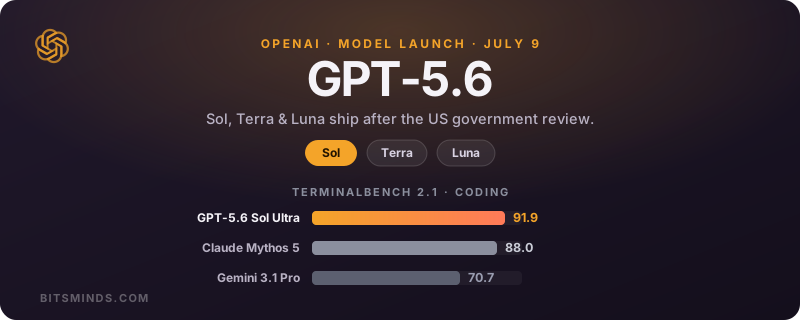
GPT-5.6 Launches After a Government Delay — and Sol Tops the Coding Charts
Models

GPT-5.6 Launches After a Government Delay — and Sol Tops the Coding Charts

OpenAI shipped GPT-5.6 on July 9 as a three-tier family — Sol, Terra, Luna — after a US-government delay. Sol tops TerminalBench 2.1 at 91.9% and is ~54% more token-efficient on agentic coding, though Anthropic's Fable 5 still leads SWE-Bench Pro.

OpenAI

Read more →
MEITUAN · OPEN-WEIGHT CODING MODEL LongCat-2.0 1.6-trillion-parameter MoE Trained and served end-to-end on ≈50,000 domestic chips — zero Nvidia GPUs. SWE-bench Pro 59.5 1M context From $0.30 / 1M 50,000 DOMESTIC CHIPS 0 × NVIDIA BITSMINDS.COM
Models

LongCat-2.0: A 1.6T Coding Model Trained on Chinese Chips

Meituan open-sourced LongCat-2.0 on June 30 — a 1.6-trillion-parameter mixture-of-experts coding model trained and served end to end on more than 50,000 Chinese-made chips, with no Nvidia hardware in the loop. After two months quietly topping OpenRouter under the alias “Owl Alpha,” the MIT-licensed model claims 59.5% on SWE-bench Pro at a fraction of GPT-5.5’s price.

VentureBeat

Read more →
GEMINI 3.5 PRO · GENERAL AVAILABILITYGoogle’s June deadline slips to JulyJUNE 202630TARGET MISSEDJULY 2026NEW WINDOWGoogle cites token-efficiency and long-horizon tuning after early-tester feedback.BITSMINDS.COMSource: TechTimes
Models

Gemini 3.5 Pro Slips to July as Google Misses Deadline

Google let its self-imposed June deadline for Gemini 3.5 Pro pass without a launch, and now says the frontier model will reach general availability in July. The company points to token-efficiency and long-horizon agentic tuning — even as a wave of senior DeepMind researchers heads for the exits.

TechTimes

Read more →
ANTHROPIC · NEW MODELClaude Sonnet 5Near-Opus coding at intro $2 / $10 per million tokens58.1Sonnet 4.663.2Sonnet 569.2Opus 4.8Agentic coding benchmark · SWE-bench Pro (%)BITSMINDS.COM
Models

Claude Sonnet 5 Lands, Closing In on Opus 4.8

Anthropic released Claude Sonnet 5 on June 30 — its most agentic mid-tier model yet, scoring 63.2% on SWE-bench Pro and matching Opus 4.8 on some knowledge work, with introductory pricing of $2/$10 per million tokens. It is now the default model on Claude’s Free and Pro plans.

Anthropic

Read more →
Ornith-1.0 cracks the open-weights coding race SWE-Bench Verified (% resolved) · MIT license · 9B / 31B / 35B / 397B 87.6 Opus 4.8 82.4 Ornith-1.0 397B 80.8 Opus 4.7 OPEN WEIGHTS BITSMINDS.COM
Models

Ornith-1.0: Open Coding Models That Self-Scaffold

DeepReinforce has open-sourced Ornith-1.0, an MIT-licensed family of coding models (9B to 397B) that learn to write their own agent scaffolds during reinforcement training. The 397B flagship resolves 82.4% of SWE-Bench Verified issues — second only to Claude Opus 4.8 — while the 9B model runs on a single 80GB GPU, putting frontier-class agentic coding within reach of self-hosters.

MarkTechPost

Read more →
GPT-5.6 ARRIVES IN THREE TIERS OpenAI ships Sol, Terra and Luna — under U.S. government limits FLAGSHIP Sol Frontier coding & security $5 / $30 in / out per 1M tokens BALANCED Terra High-volume business tasks $2.50 / $15 in / out per 1M tokens EFFICIENT Luna Fast, low-cost everyday work $1 / $6 in / out per 1M tokens BITSMINDS.COM
Models

GPT-5.6 Is Here: OpenAI Ships Sol, Terra and Luna

OpenAI released GPT-5.6 on June 27 as a three-model family — the flagship Sol, the balanced Terra and the fast, cheap Luna — but only as a limited preview to about 20 U.S. government-approved partners. Sol leads agentic-coding benchmarks (91.9% on Terminal-Bench 2.1) and matches prior security results using roughly a third of the output tokens, with general availability promised in the coming weeks.

OpenAI

Read more →
BYTEDANCE LAUNCHES SEED 2.1 Doubao Seed 2.1 Pro & Turbo — built for the coding and agent era #8 WORLDWIDE CODE ARENA: FRONTEND 1539 Draws level with Claude Opus 4.6 JUN 24 “comparable to GPT-5.5” on Volcano Engine Pro ¥6/¥30 · Turbo ¥3/¥15 BITSMINDS.COM
Models

ByteDance’s Seed 2.1 Pro Pulls Level With Claude Opus 4.6

ByteDance launched its Doubao Seed 2.1 Pro and cheaper Turbo models on June 24, built for the “coding and agent era.” Seed 2.1 Pro scored 1539 on the Code Arena: Frontend leaderboard — eighth in the world and level with Claude Opus 4.6 — while ByteDance claims three core capabilities are comparable to GPT-5.5.

AIbase

Read more →
MODEL WATCH · ANTHROPIC · RUMORED JUN 24 Claude Sonnet 5 — rumored. 'Fennec' is floated for the week of June 23 — but Anthropic has confirmed nothing. 60% LAUNCH ODDS BitsMinds estimate for this week — not a market WHAT'S RUMORED Codename 'Fennec', from a leaked log SWE-Bench around 82–92% — estimated Feb's 'Fennec' shipped as Sonnet 4.6 BITSMINDS.COM Rumor · Vertex AI leak · Crypto Briefing
Models

Claude Sonnet 5 Rumors Resurface — Still Nothing Confirmed

Reports this week floated Claude Sonnet 5 (codename 'Fennec') for the week of June 23, alongside GPT-5.6 — but Anthropic has confirmed nothing. And the same 'Sonnet 5' leak in February shipped as Sonnet 4.6, a reminder to read codenames with caution.

Crypto Briefing

Read more →
SAKANA · FUGU One Model to Orchestrate the Rest T THINKER W WORKER V VERIFIER S SYNTHESIZER FUGU BITSMINDS.COM
Models

Sakana AI's Fugu Turns Model Orchestration Into a Product

The Tokyo lab made Fugu generally available on June 22 — a foundation model trained to command a pool of other AIs through one OpenAI-compatible API, pitched as a hedge against single-vendor lock-in.

Sakana AI

Read more →
Z GLM-5.2 by Z.ai · MODEL REVIEW 62.1 SWE-bench Pro #1 open model · beats GPT-5.5 74.4 FrontierSWE ≈ Opus 4.8 (75.4) Open-weight · MIT · 744B MoE · 1M context BITSMINDS.COM
Models

GLM-5.2 Review: The Open Model That Out-Codes GPT-5.5

GLM-5.2 is the strongest open-weight coding model yet: MIT-licensed, 744B MoE, 1M context. It beats GPT-5.5 on SWE-bench Pro and trails Opus 4.8 by a point on FrontierSWE — at a fraction of the cost. Our review, with benchmark charts.

The Decoder

Read more →
GPT-5.6 WHAT WE KNOW SO FAR — STATUS: UNCONFIRMED NOW Pre-train Canary Red-team Early access Launch CODEX ROUTING LOG ▸ route: gpt-5.6 · seen May 13 ▸ route: gpt-5.5 · then reverted Rumored · 1.5M context Rumored · ~1/3 cheaper vs Fable 5 Odds 83% · Jun 22–28 BITSMINDS.COM
Models

GPT-5.6: Everything We Know — Now Launched as Sol, Terra & Luna

GPT-5.6 is here: OpenAI shipped it on July 9, 2026 as a three-tier family — Sol, Terra and Luna — after a rare US-government delay, with Sol topping several agentic-coding charts. Here's the confirmed launch plus the full pre-launch rumor trail that got us here.

WaveSpeed Blog

Read more →
MiMo-V2-Pro Xiaomi · API-only reasoning model 49 INTELLIGENCE INDEX 1M-token context #10 worldwide $1 / $3 per 1M tokens MI BITSMINDS.COM
Models

Xiaomi's MiMo-V2-Pro Cracks the Global Top 10 for AI Reasoning — at a Fraction of the Price

Xiaomi's reasoning model scores 49 on the Artificial Analysis Intelligence Index — #10 worldwide, between Kimi K2.5 and GLM-5 — while running its whole benchmark suite for just $348.

Artificial Analysis

Read more →
MODEL WATCH · OPENAI · LEAKS, UNCONFIRMED JUN 17 GPT-5.6 looks days away — if the leaks hold. Prediction markets put a late-June launch near 83% — but OpenAI has confirmed nothing. 83% LAUNCH ODDS Polymarket · June 22–28 window RUMORED SPECS Context window up to ~1.5M tokens Stronger agentic coding, a leaker claims Pricing rumored near a third of Fable 5 BITSMINDS.COM Source: Polymarket · Cryptopolitan · leaks
Models

GPT-5.6 Rumors Reach a Fever Pitch: Prediction Markets Bet on a Late-June Launch, Leaks Claim a 1.5M-Token Window

No OpenAI announcement exists yet, but developer leaks and prediction markets now point to a GPT-5.6 launch in late June — Polymarket prices the June 22–28 window near 83% — with rumored upgrades including a ~1.5M-token context and stronger agentic coding. Treat it all as unconfirmed.

Cryptopolitan

Read more →
ZHIPU / Z.AI · OPEN MODEL JUN 16 GLM-5.2 goes open under MIT. A 744B-parameter MoE built for long-horizon agentic coding. 744B TOTAL · 40B ACTIVE (MoE) 1M CONTEXT TOKENS 131K MAX OUTPUT TOKENS MIT OPEN-WEIGHTS LICENSE No benchmarks published at launch — performance is a vendor claim. glm-5.2[1m] · 28.5T training tokens · agentic coding BITSMINDS.COM Source: Z.ai
Models

Zhipu Releases GLM-5.2: a 744B-Parameter, 1M-Token Coding Model Under a Full MIT License

Zhipu (Z.ai) has launched GLM-5.2, a 744B-parameter Mixture-of-Experts model (40B active) with a 1M-token context window, built for agentic coding and released under a permissive MIT license. The catch: no benchmarks were published at launch, so performance claims remain vendor assertions for now.

Z.ai

Read more →
Moonshot AI Ships Kimi K2.7-Code, an Open-Weight Coding Model It Says Uses 30% Fewer Reasoning Tokens
Models

Moonshot AI Ships Kimi K2.7-Code, an Open-Weight Coding Model It Says Uses 30% Fewer Reasoning Tokens

The Beijing lab’s fifth K2 release in a year is a coding-first, 1-trillion-parameter open-weight model under a modified MIT license — but independent testers say the headline benchmarks are Moonshot’s own and don’t all hold up.

Crypto Briefing

Read more →
BITSMINDS.COM
ModelsLab

Fable 5 vs Opus 4.8, One Prompt Each: Four Builds, Dead Level at 2–2

We pasted identical prompts into Claude Opus 4.8 and Claude Fable 5 — an animated highway interchange, a one-file Space Invaders, a pure-SVG aquarium, and a 3D rocket launch — one shot each, no retries. Everything runs live inside the article. Four builds in, it is dead level at 2–2 — and the launch round flips the very pattern the first three revealed.

BitsMinds Lab

Read more →
BITSMINDS VERDICT Claude Fable 5 The most capable public model yet — for a premium 4.6 OUT OF 5 ★★★★½ SWE-Bench Pro 80.3 Humanity's Last Exam 59.0 Blueprint-Bench 2 38.6 Fable 5 headline benchmarks — higher is better BITSMINDS.COM
Models

Review: Claude Fable 5 Is the Most Capable Public Model Yet — for a Premium

Anthropic's Claude Fable 5 is the most capable model the public can use today — topping SWE-Bench Pro and excelling at vision and long tasks. It is also the priciest major model and ships with hard safety guardrails. Our first-look verdict.

BitsMinds Reviews

Read more →